
ModelsArchitectures & capability
Show Lab's SolarRenderer turns layouts, depth maps and poses into realistic video in four steps, with code, weights and data released
SolarRenderer adds two LoRAs to the 33B MiniMax-H3 video model. Rough structure inputs such as grey-box game scenes, depth maps, skeletons and sketches become realistic 1344×768 video in four denoising steps, and a streaming variant targets real-time rendering.
From the huggingface.co article of October 21, 2026 and cited sources: Structure videos go into the backbone's existing reference pathway, lined up with the frames they describe. [3]
 AT Pulse research deskPublished · Updated · 4 min read · AI-assisted analysis
AI-assisted, not human-edited. Methodology Corrections Who owns this site
- What happened
- Structure videos go into the backbone's existing reference pathway, lined up with the frames they describe. [3]
- Original source
- huggingface.co article, company source
- Brief by
- AT Pulse research desk AI-assisted; publisher and contact on the desk page
- When
- October 21, 2026 article published
- Covered
- Oct 22 edition
- Evidence
- 11 sources across 7 sites
Reach: not measured yet
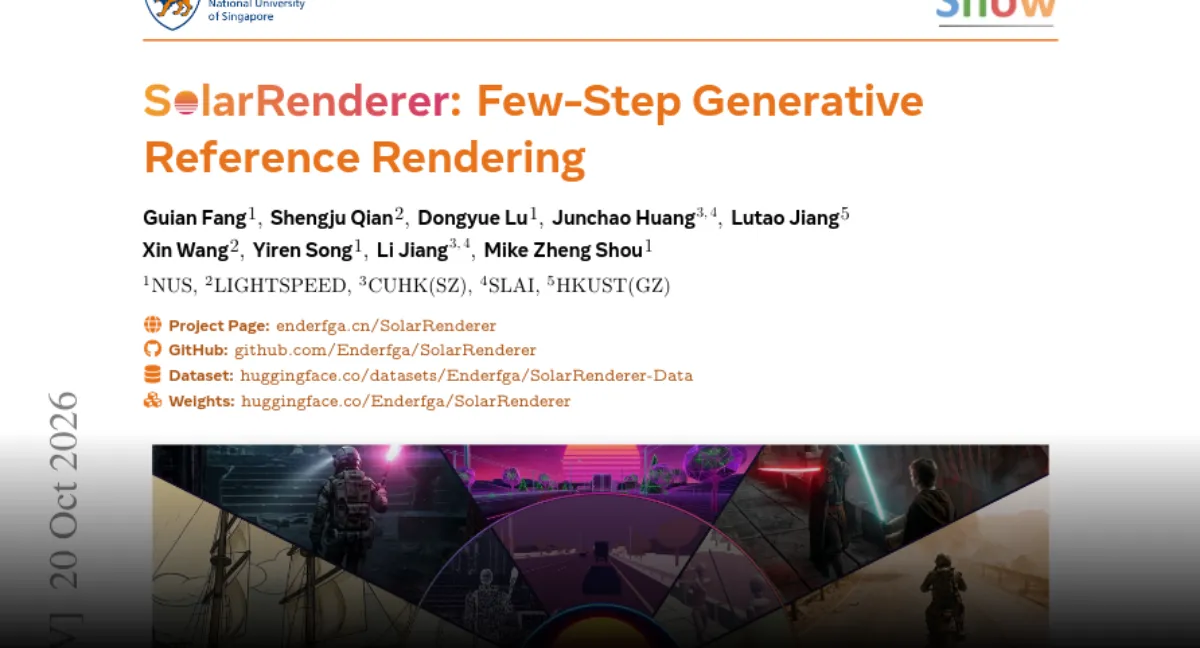
Structure videos go into the backbone's existing reference pathway, lined up with the frames they describe. A plain-text prompt says what kind of input each one is, so a single control LoRA can handle many structure types. The paper reports that it works on 11 of 16 tested structure types that were absent from training. [3]
The speed comes from starting with a pretrained four-step LoRA and adding structure-guided distribution matching. The paper reports this is 12.3× faster than 50-step sampling while keeping the learned control. A block-causal streaming variant with a KV cache renders each 17-frame chunk in 0.70 s, about 1.1 s behind the input. [3] [1]
These results are the authors' own and have not been replicated by others. A Gemini model judged pairwise comparisons on the authors' benchmark of 208 generalization cases and 53 in-distribution clips. SolarRenderer ranked first of ten methods on structure fidelity, with an Elo of 1313. Its overall visual-quality Elo was about 1428–1441, against about 1221 for PAI ControlNet-Union. [1] [9]
open code and LoRAs let teams test a general video model as a final rendering pass over grey-box scenes without training per engine. Implication: game and simulation teams could prototype quickly, but licensing and memory needs limit production use.
Executive brief
SolarRenderer's weights are open, but their license excludes the United States, the European Union, the United Kingdom and South Korea (HF model card). That limits who can legally use it. The system comes from Show Lab authors including Mike Zheng Shou. It takes rough structure videos, such as grey-box game scenes, depth maps, skeletons and sketches, and turns them into realistic video in four denoising steps. A streaming version renders 768p video in real time (arXiv). The code, LoRA weights, a training-data subset and a benchmark are all public. No independent evaluation or press coverage was found, so every performance number below comes from the authors.
What changed and event timeline
Real-time generative rendering arrives
AlayaRenderer-Flash reported turning game-engine buffers into video at 31.54 FPS on an NVIDIA H200, a 56× speedup over its teacher model. This set the bar SolarRenderer now enters against.
MiniMax H3 announced
MiniMax announced an omni-modal model that handles reference-based video generation and editing through natural-language instructions, and said it planned to open the weights.
FlashRender sets the few-step precedent
FlashRender reported quality equal to multi-step baselines at 25× lower sampling cost for re-filming a video along a new camera path.
SolarRenderer paper submitted
The arXiv submission describes two LoRAs on a frozen 33B MiniMax-H3 backbone and a 136K-clip training corpus. On the same day, a user reported running out of memory on an 80 GB A800.
More detail
Paper page and low-memory path
The Hugging Face paper page went up. Maintainers released a ComfyUI workflow that fits about 16 GB of GPU memory using 8-bit weights.
More detail
Capabilities and access
- Inputs: a structure video, plus an optional first frame and a text prompt that set the look. Output: 1344×768 video at 24 fps.
- Released files: a control LoRA, a four-step LoRA and causal streaming variants. The code is Apache 2.0.
- Streaming: each 17-frame chunk takes 0.70 s, running about 1.1 s behind the input (HF post).
Read the full section
- Inputs: a structure video, plus an optional first frame and a text prompt that set the look. Output: 1344×768 video at 24 fps. A full clip takes about 3.5 minutes on one GPU (model card).
- Released files: a control LoRA, a four-step LoRA and causal streaming variants. The code is Apache 2.0. The weights fall under the MiniMax H3 Community License (GitHub).
- Streaming: each 17-frame chunk takes 0.70 s, running about 1.1 s behind the input (HF post). None of the reviewed sources name the GPU behind this real-time figure.
Technical analysis for researchers and developers
- Conditioning: structure videos enter the backbone's existing reference pathway at the positions of the frames they describe. There is no type tag.
- Speed-up: the team starts from a pretrained four-step LoRA and adds structure-guided distribution matching.
- Streaming: a block-causal variant with a KV cache renders indefinitely.
Read the full section
- Conditioning: structure videos enter the backbone's existing reference pathway at the positions of the frames they describe. There is no type tag; plain text says what the input is, so one control LoRA can handle many kinds of structure (arXiv).
- Speed-up: the team starts from a pretrained four-step LoRA and adds structure-guided distribution matching. This keeps the learned control while running 12.3× faster than 50-step sampling.
- Streaming: a block-causal variant with a KV cache renders indefinitely.
- Evaluation: a Gemini model judges pairwise comparisons and the results are converted to Elo scores. The test sets are 208 generalization cases and 53 in-distribution clips. The authors say human judges validated the Gemini judgments (project page).
Claims and evidence
All of these numbers are reported by the authors and scored mainly by an LLM judge on the authors' own benchmark. No third-party replication was found.
Read the full section
- Structure fidelity: ranked first among ten methods with an Elo of 1313 (HF post).
- Visual quality: overall Elo of about 1428–1441, against about 1221 for PAI ControlNet-Union and about 580 for StreamRender-H3 (project page).
- Generalization: works on 11 structure types never seen in training, out of 16 tested (arXiv).
All of these numbers are reported by the authors and scored mainly by an LLM judge on the authors' own benchmark. No third-party replication was found.
Context and prior work
- The project is part of a fast-moving 2026 line of "generative rendering" work: AlayaRenderer-Flash for real-time G-buffer-to-video (Emergent Mind) and FlashRender for few-step distillation (FlashRender).
- It is compared against Cosmos-Transfer, Wan2.2-VACE-Fun and Streaming CWM, among others (project page).
- The new element is building on a general-purpose open video model, MiniMax-H3 (fal.ai), instead of a renderer tied to one engine.
Read the full section
- The project is part of a fast-moving 2026 line of "generative rendering" work: AlayaRenderer-Flash for real-time G-buffer-to-video (Emergent Mind) and FlashRender for few-step distillation (FlashRender).
- It is compared against Cosmos-Transfer, Wan2.2-VACE-Fun and Streaming CWM, among others (project page).
- The new element is building on a general-purpose open video model, MiniMax-H3 (fal.ai), instead of a renderer tied to one engine.
Limitations, safety and contested findings
- Data mismatch: the paper describes 136K clips, including YouTube footage. The UnrealZoo portion is non-commercial (CC BY-NC 4.0) (dataset card).
- Memory: the model card says a clip takes about 3.5 minutes on one GPU.
- Speed: the real-time claim does not name its hardware.
Read the full section
- Data mismatch: the paper describes 136K clips, including YouTube footage. The released dataset has 57,738 clips from Magpie, CARLA and UnrealZoo, with no YouTube source. The UnrealZoo portion is non-commercial (CC BY-NC 4.0) (dataset card).
- Memory: the model card says a clip takes about 3.5 minutes on one GPU. The maintainers, however, say even 80 GB cards need multi-GPU sharding unless the ComfyUI path is used (GitHub issue).
- Speed: the real-time claim does not name its hardware.
Business and practitioner implications
- Game and simulation teams could use this to put a "neural final pass" over grey-box scenes without training a model per game (GitHub).
- Licensing: weight use is excluded in the US, EU, UK and Korea under the license (model card).
- Costs: expect H3-class infrastructure, or accept the quality and speed trade-offs of 8-bit weights.
Read the full section
- Game and simulation teams could use this to put a "neural final pass" over grey-box scenes without training a model per game (GitHub).
- Licensing: weight use is excluded in the US, EU, UK and Korea under the license (model card). Major markets therefore need legal review before deployment, and the non-commercial data subset adds a separate constraint.
- Costs: expect H3-class infrastructure, or accept the quality and speed trade-offs of 8-bit weights.
- Before relying on the claims: check the 208-case benchmark on your own content.